

👋 Hey, Linas here! Every day, I break down 3 stories shaping the future of FinTech & Artificial Intelligence - plus the money movements and trends worth tracking. First time here? 400k+ FinTech and AI leaders get this daily. Join them:
For six days, nobody knew who built the most-used AI model on OpenRouter.
On August 20, 2026, a listing called “Ox Alpha” appeared on OpenRouter and OpenCode: free, no owner listed, no model card, a 1M-token context window, and text, image, and video input. 6 days later, it was the most-used model on the platform, having processed about 23 trillion tokens, the biggest launch in OpenRouter’s history at roughly 2.3 times the volume of the next model.
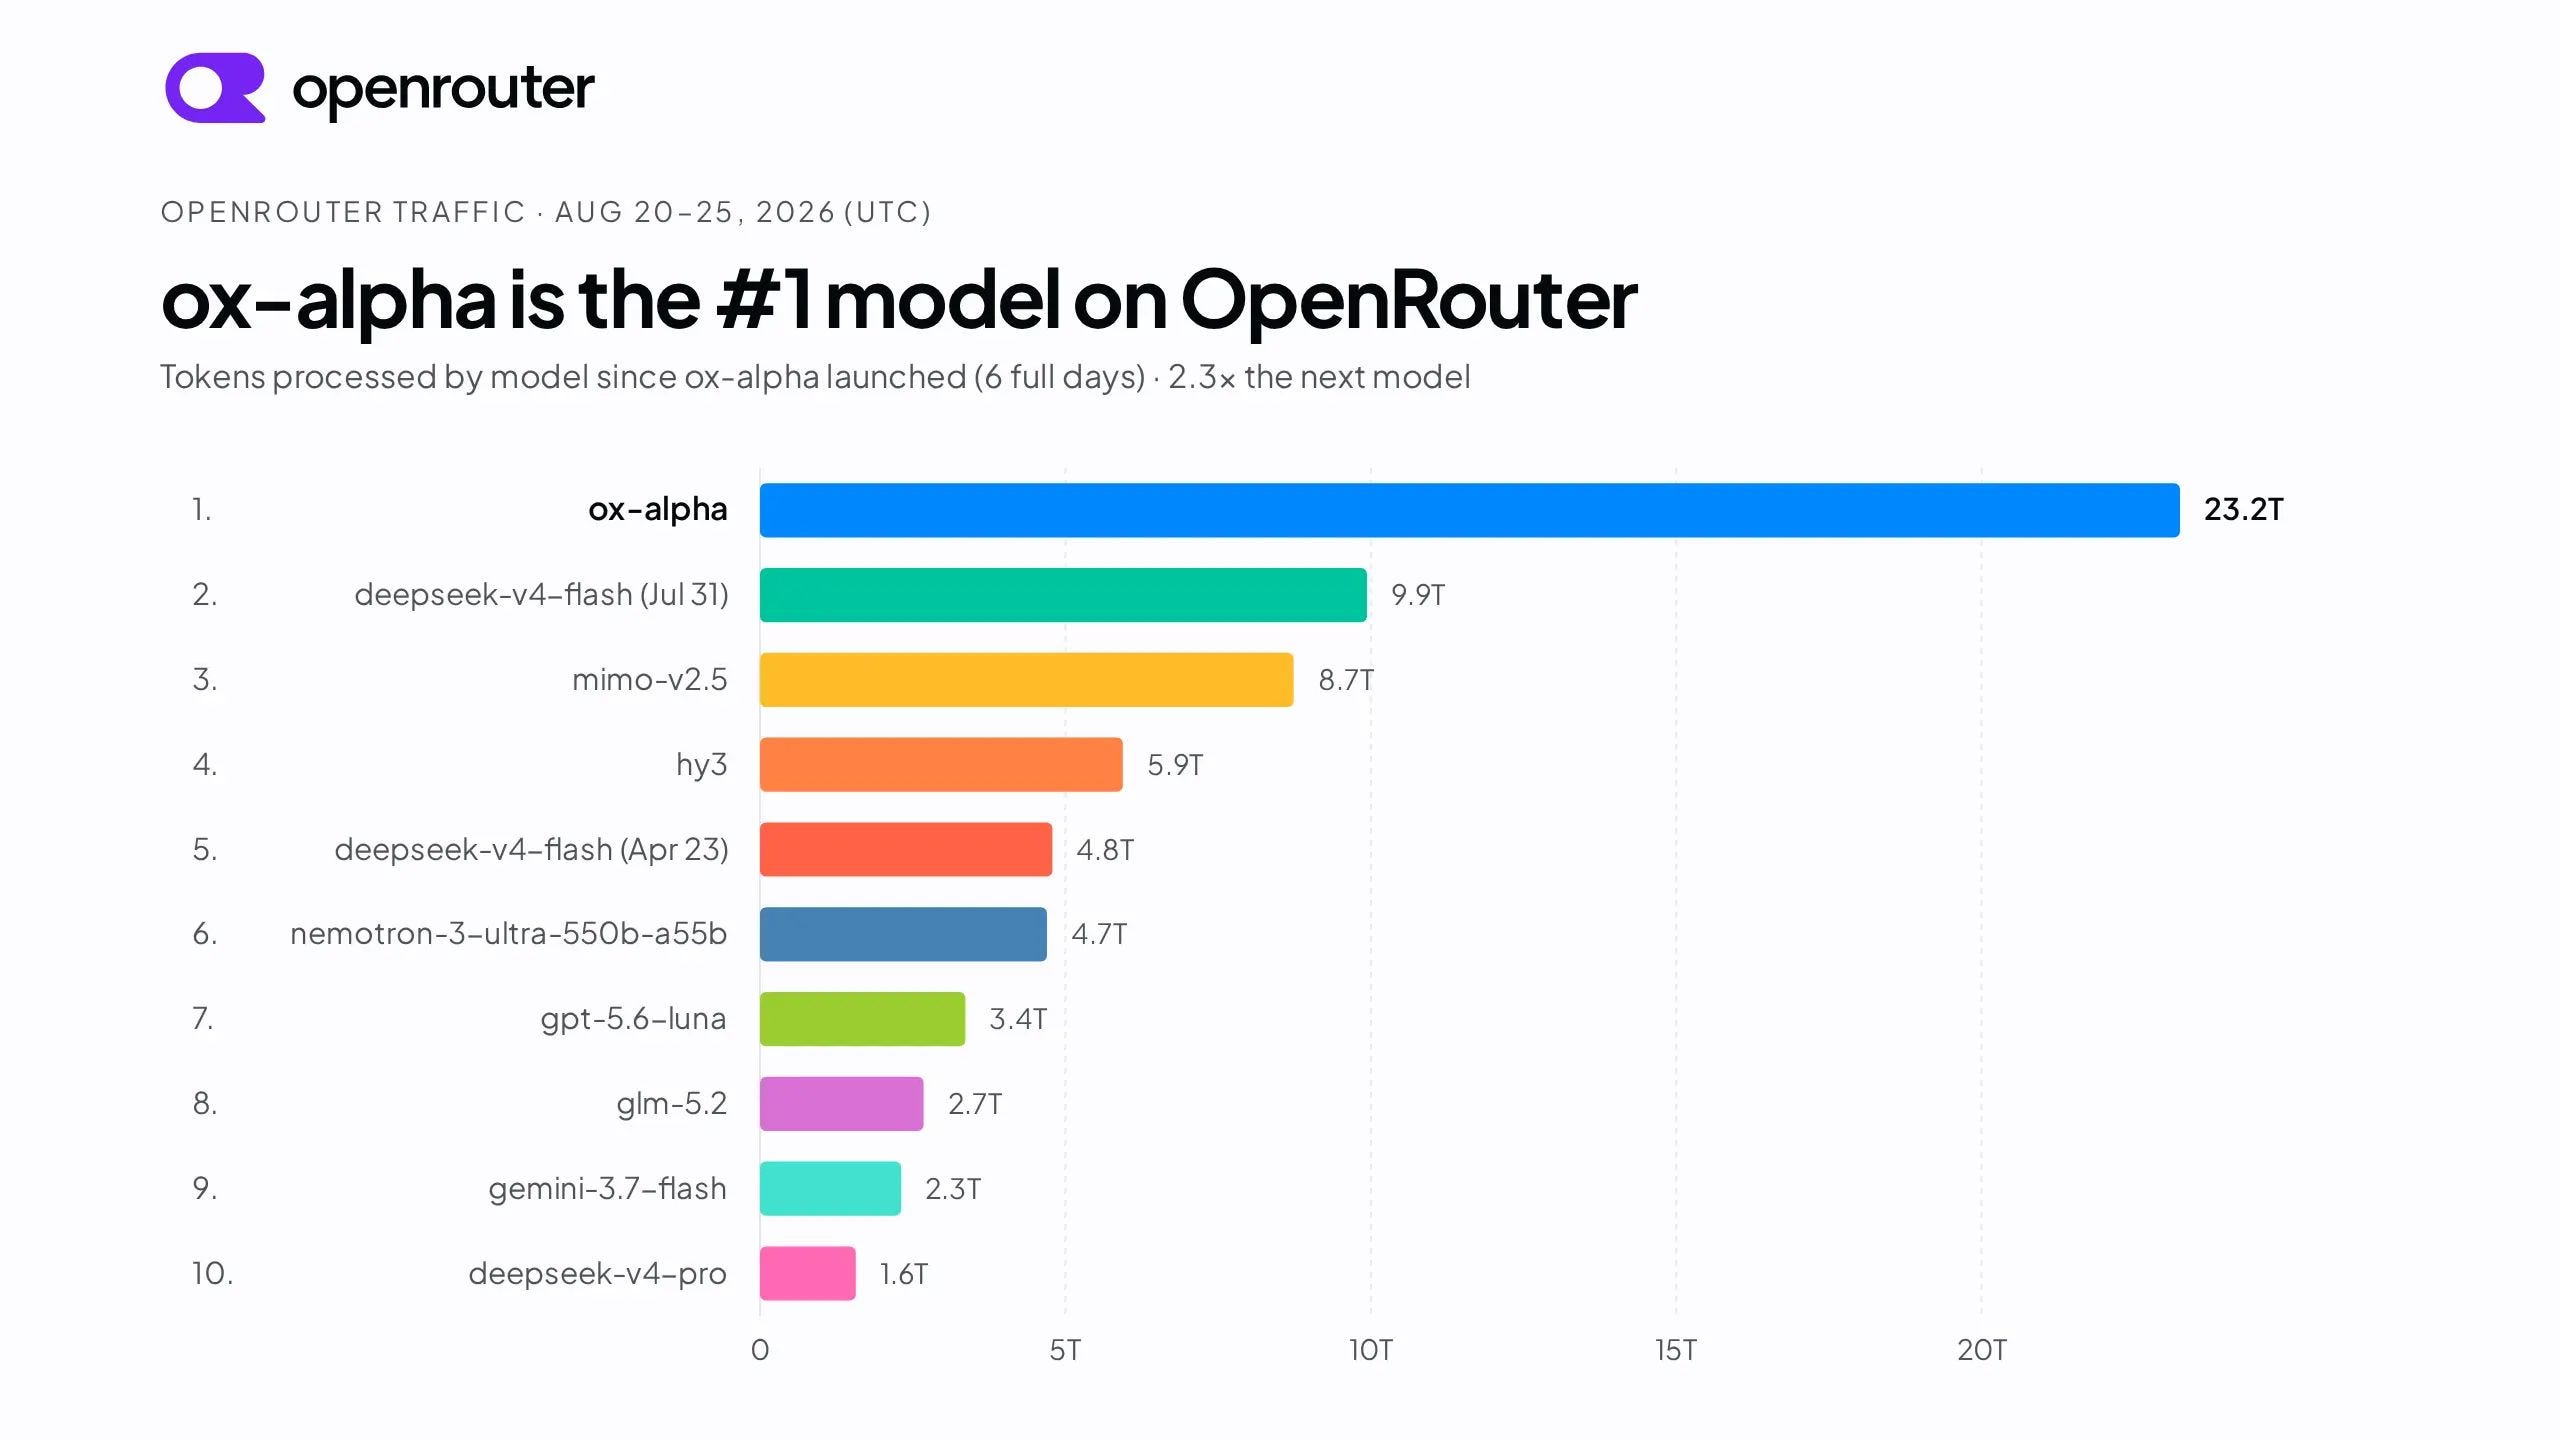
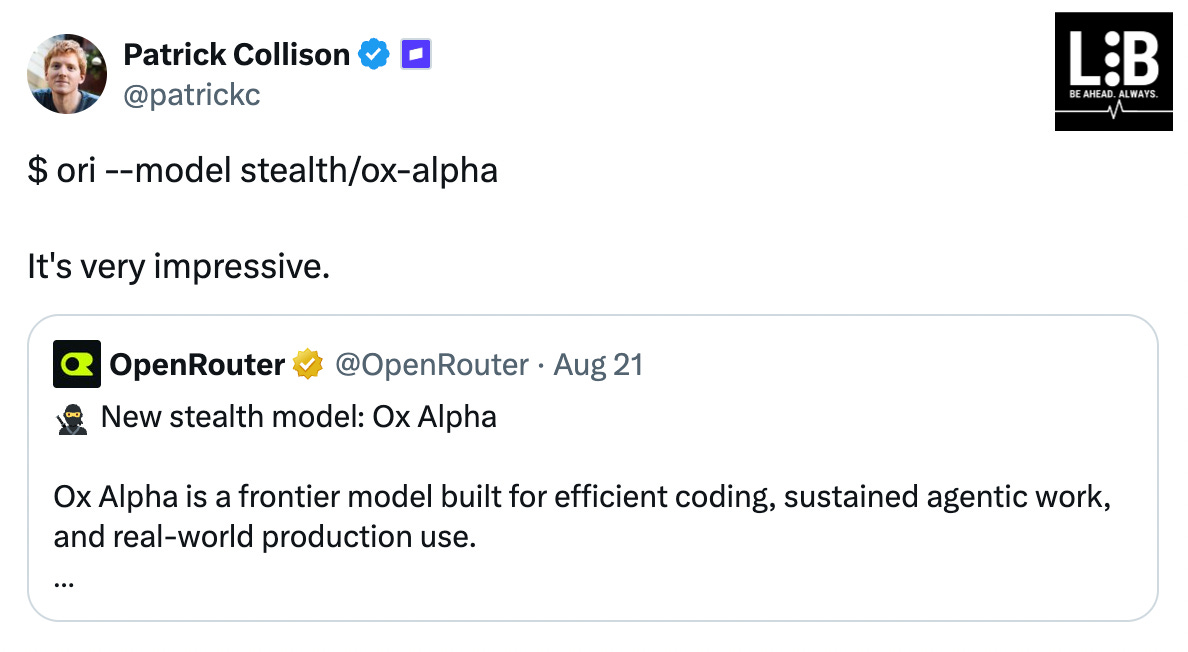
On OpenCode, it ended DeepSeek’s 56-day run at the top. Stripe had agreed to buy OpenRouter the day before the model appeared, and Stripe CEO Patrick Collison even called it very impressive.
On August 26, Bloomberg confirmed it. Ox Alpha was GLM-5.3-Flash from Zhipu AI, the Beijing lab that operates internationally as Z.ai (we will use Zhipu & ZAI for simplicity's sake going forward):
→ 320 billion parameters, 18 billion active per token
→ The first natively multimodal model in the GLM-5 series, and
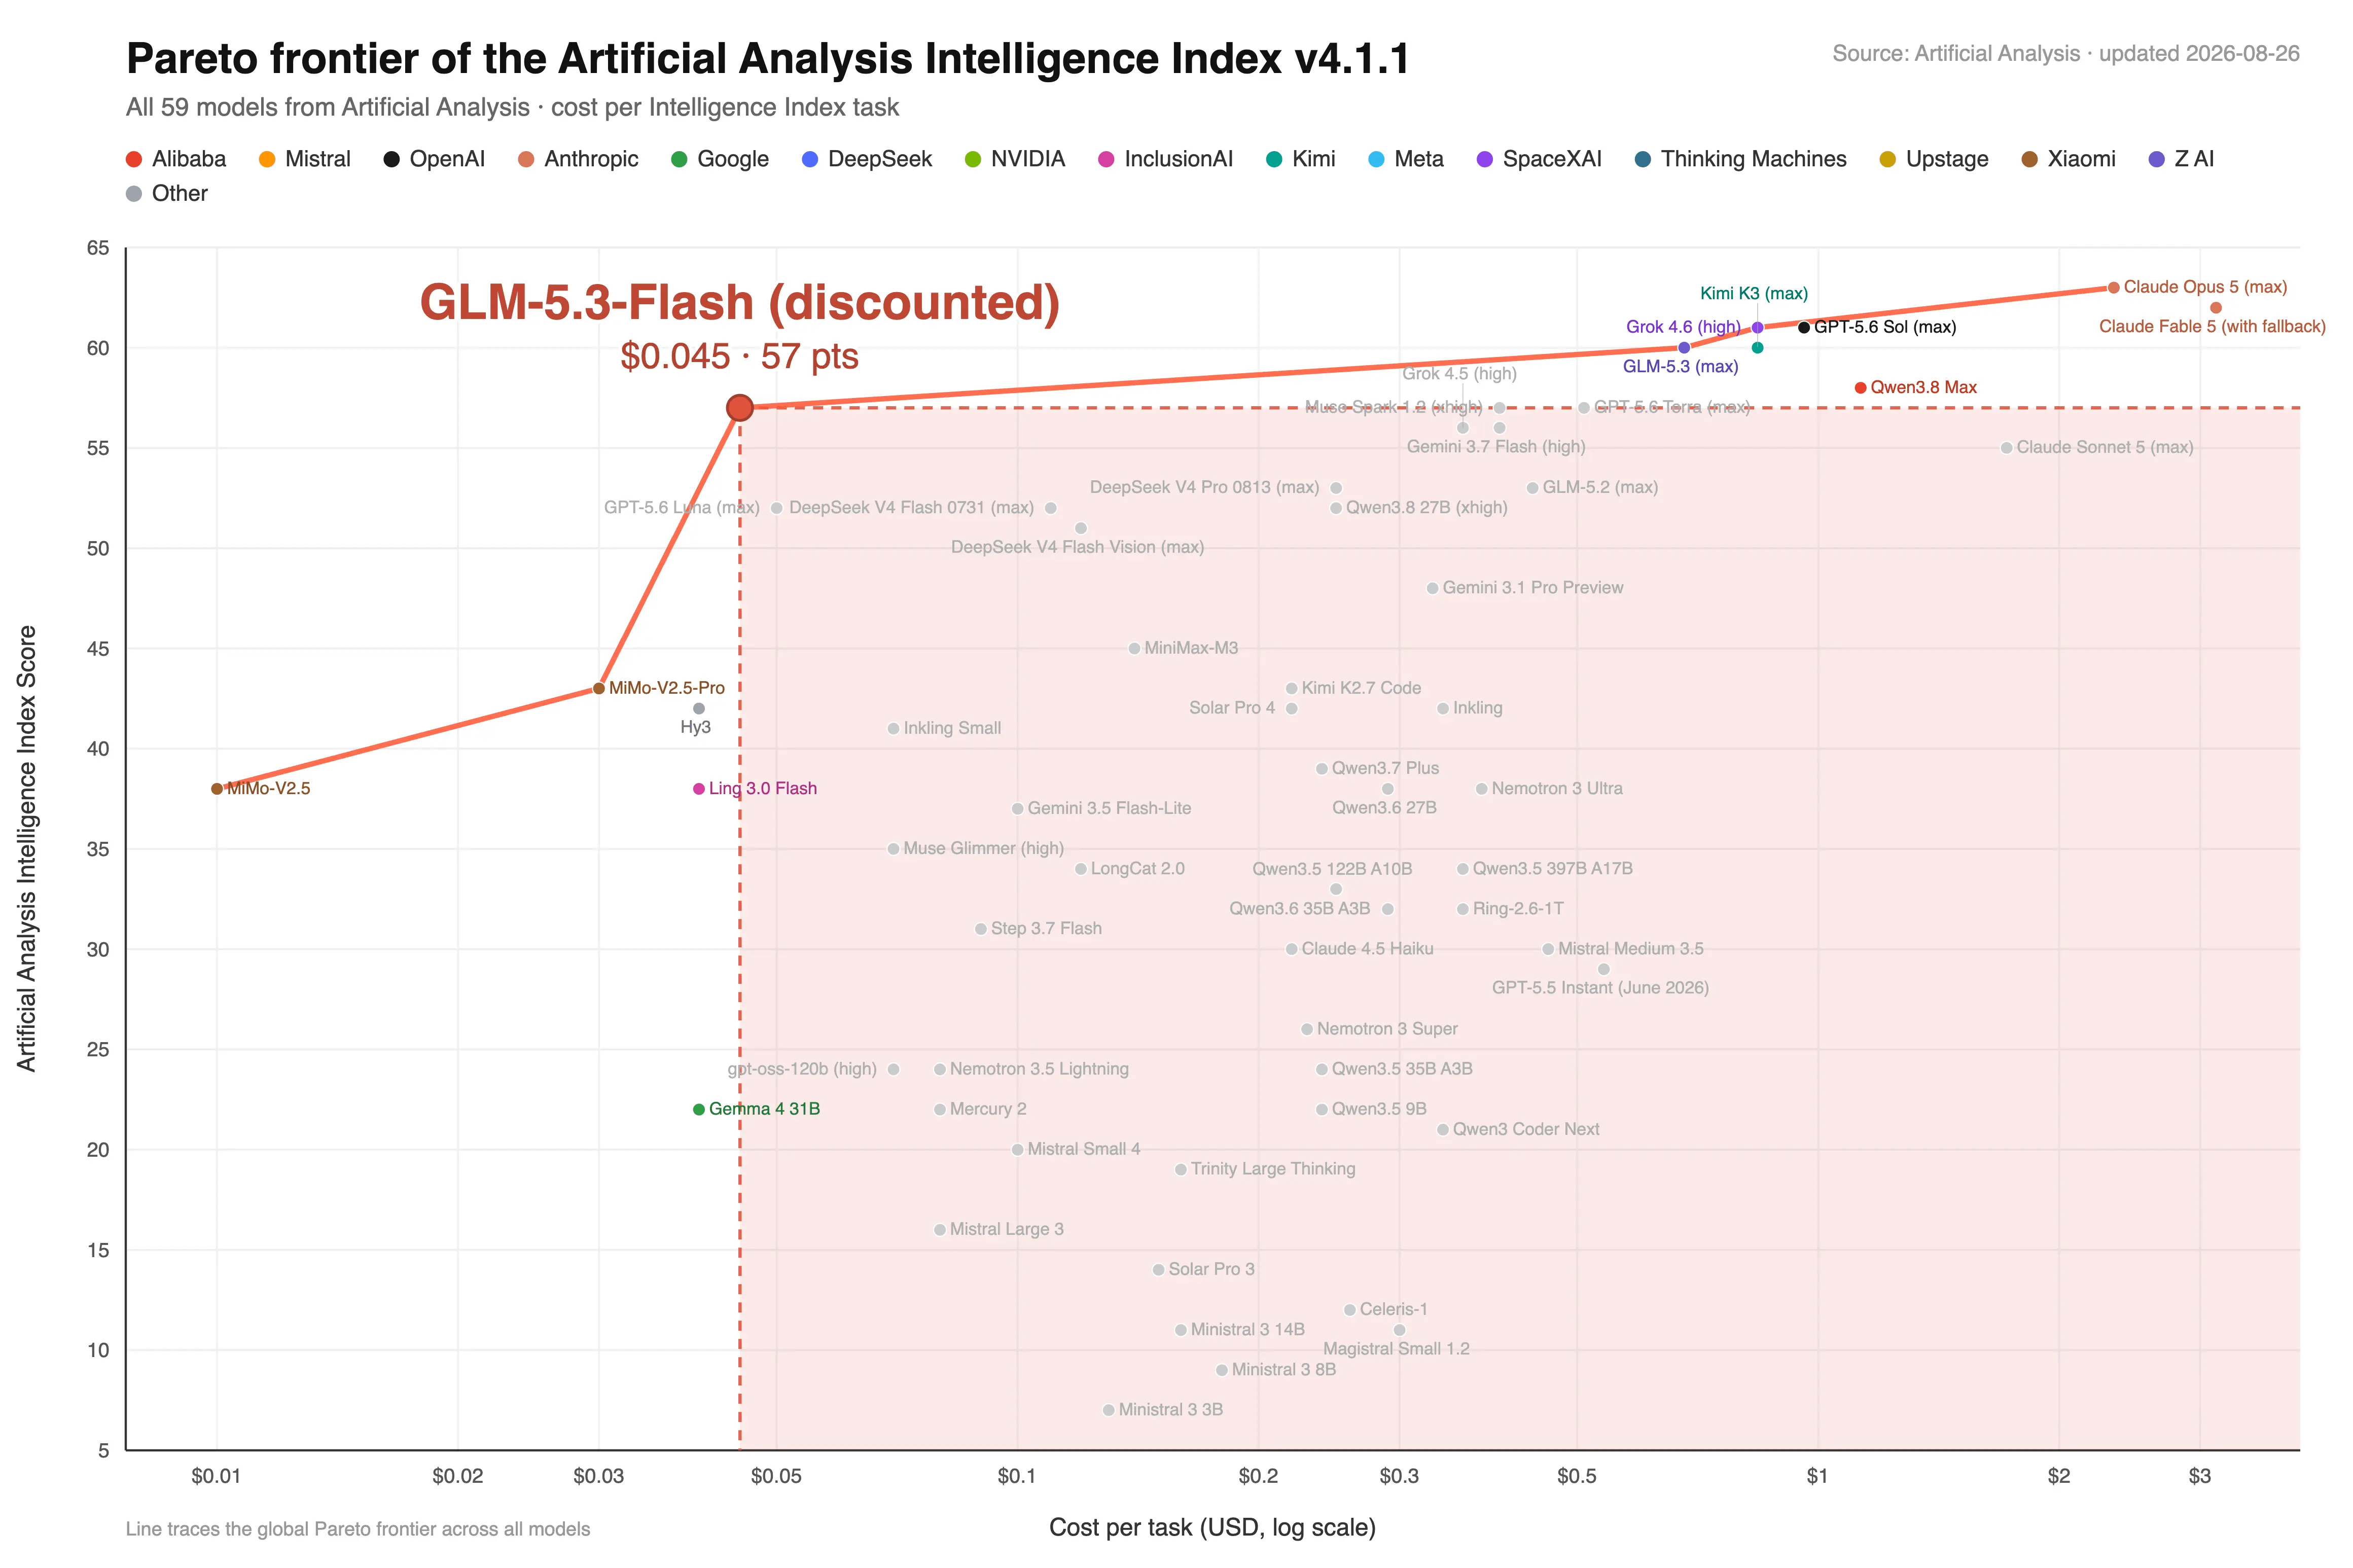
→ The cheapest model at its score on Artificial Analysis’s Intelligence Index.
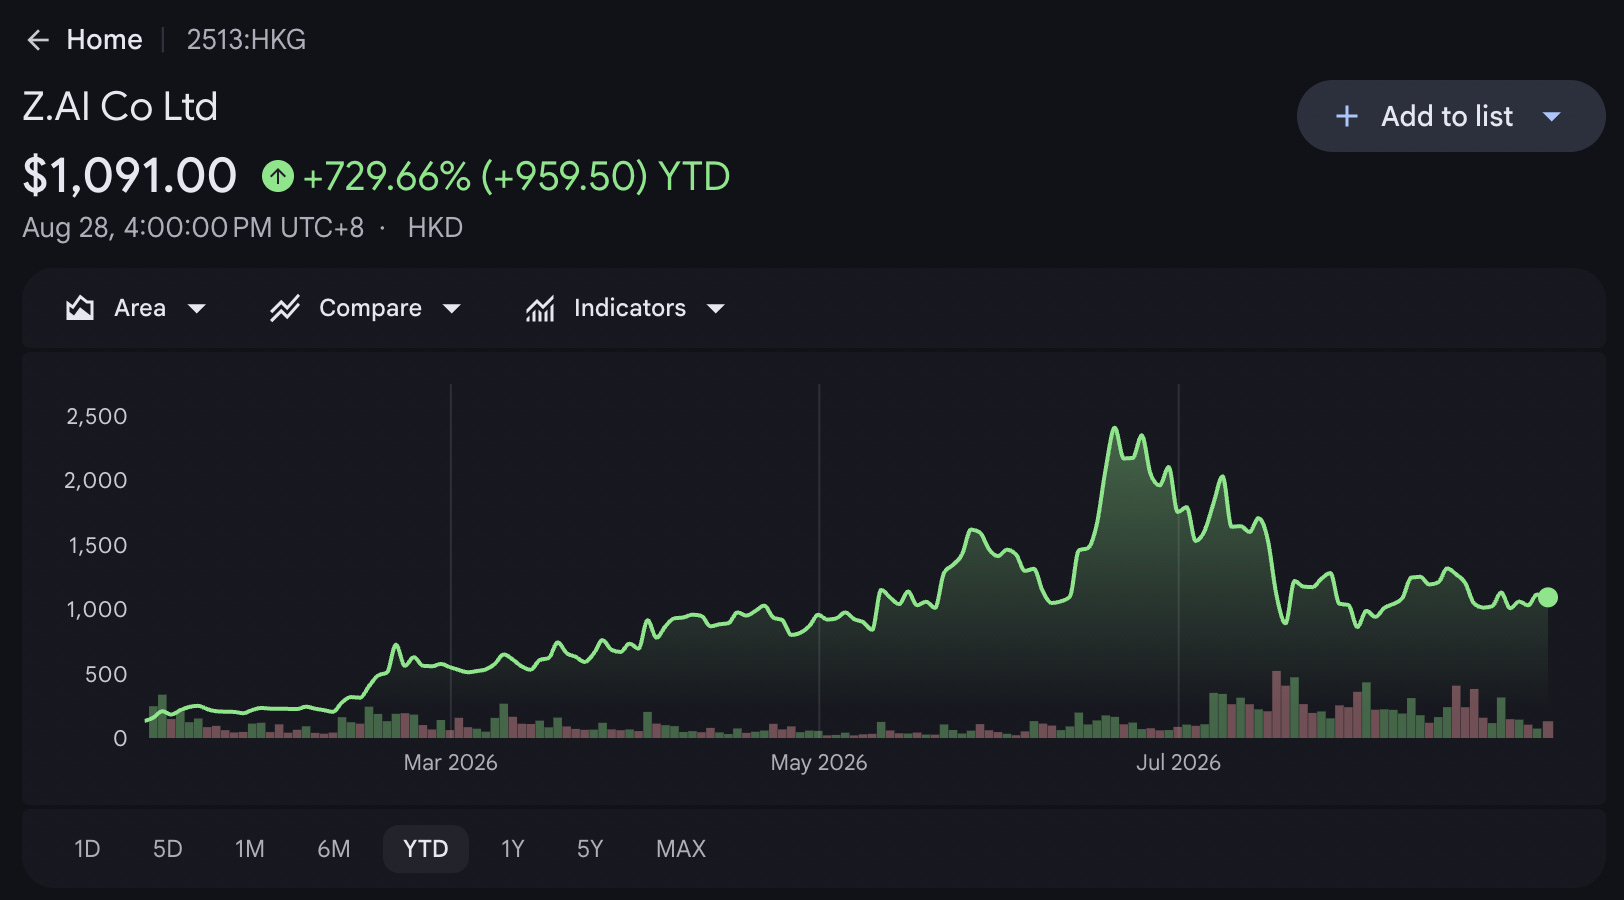
Weights landed on Hugging Face under an MIT license that same evening, and Zhipu’s Hong Kong shares closed more than 12% higher the next day, roughly 10x January’s IPO price. Not too shabby!
The numbers that matter: GLM-5.3-Flash pushed the Pareto frontier for intelligence per dollar. It scores 57 on the Artificial Analysis Intelligence Index against 60 for the ten-times-pricier GLM-5.3, tying Claude Opus 4.8 at about a twentieth of Opus’s per-task cost at list ($0.09 versus $1.78) and about a fortieth at the promotional rate ($0.045). Let that sink in! 😳
The architecture is the how here: 3x less attention compute and a 4.4x smaller KV cache than GLM-5.3 at 1M-token context. In other words, intelligence is getting cheaper, brutally fast.
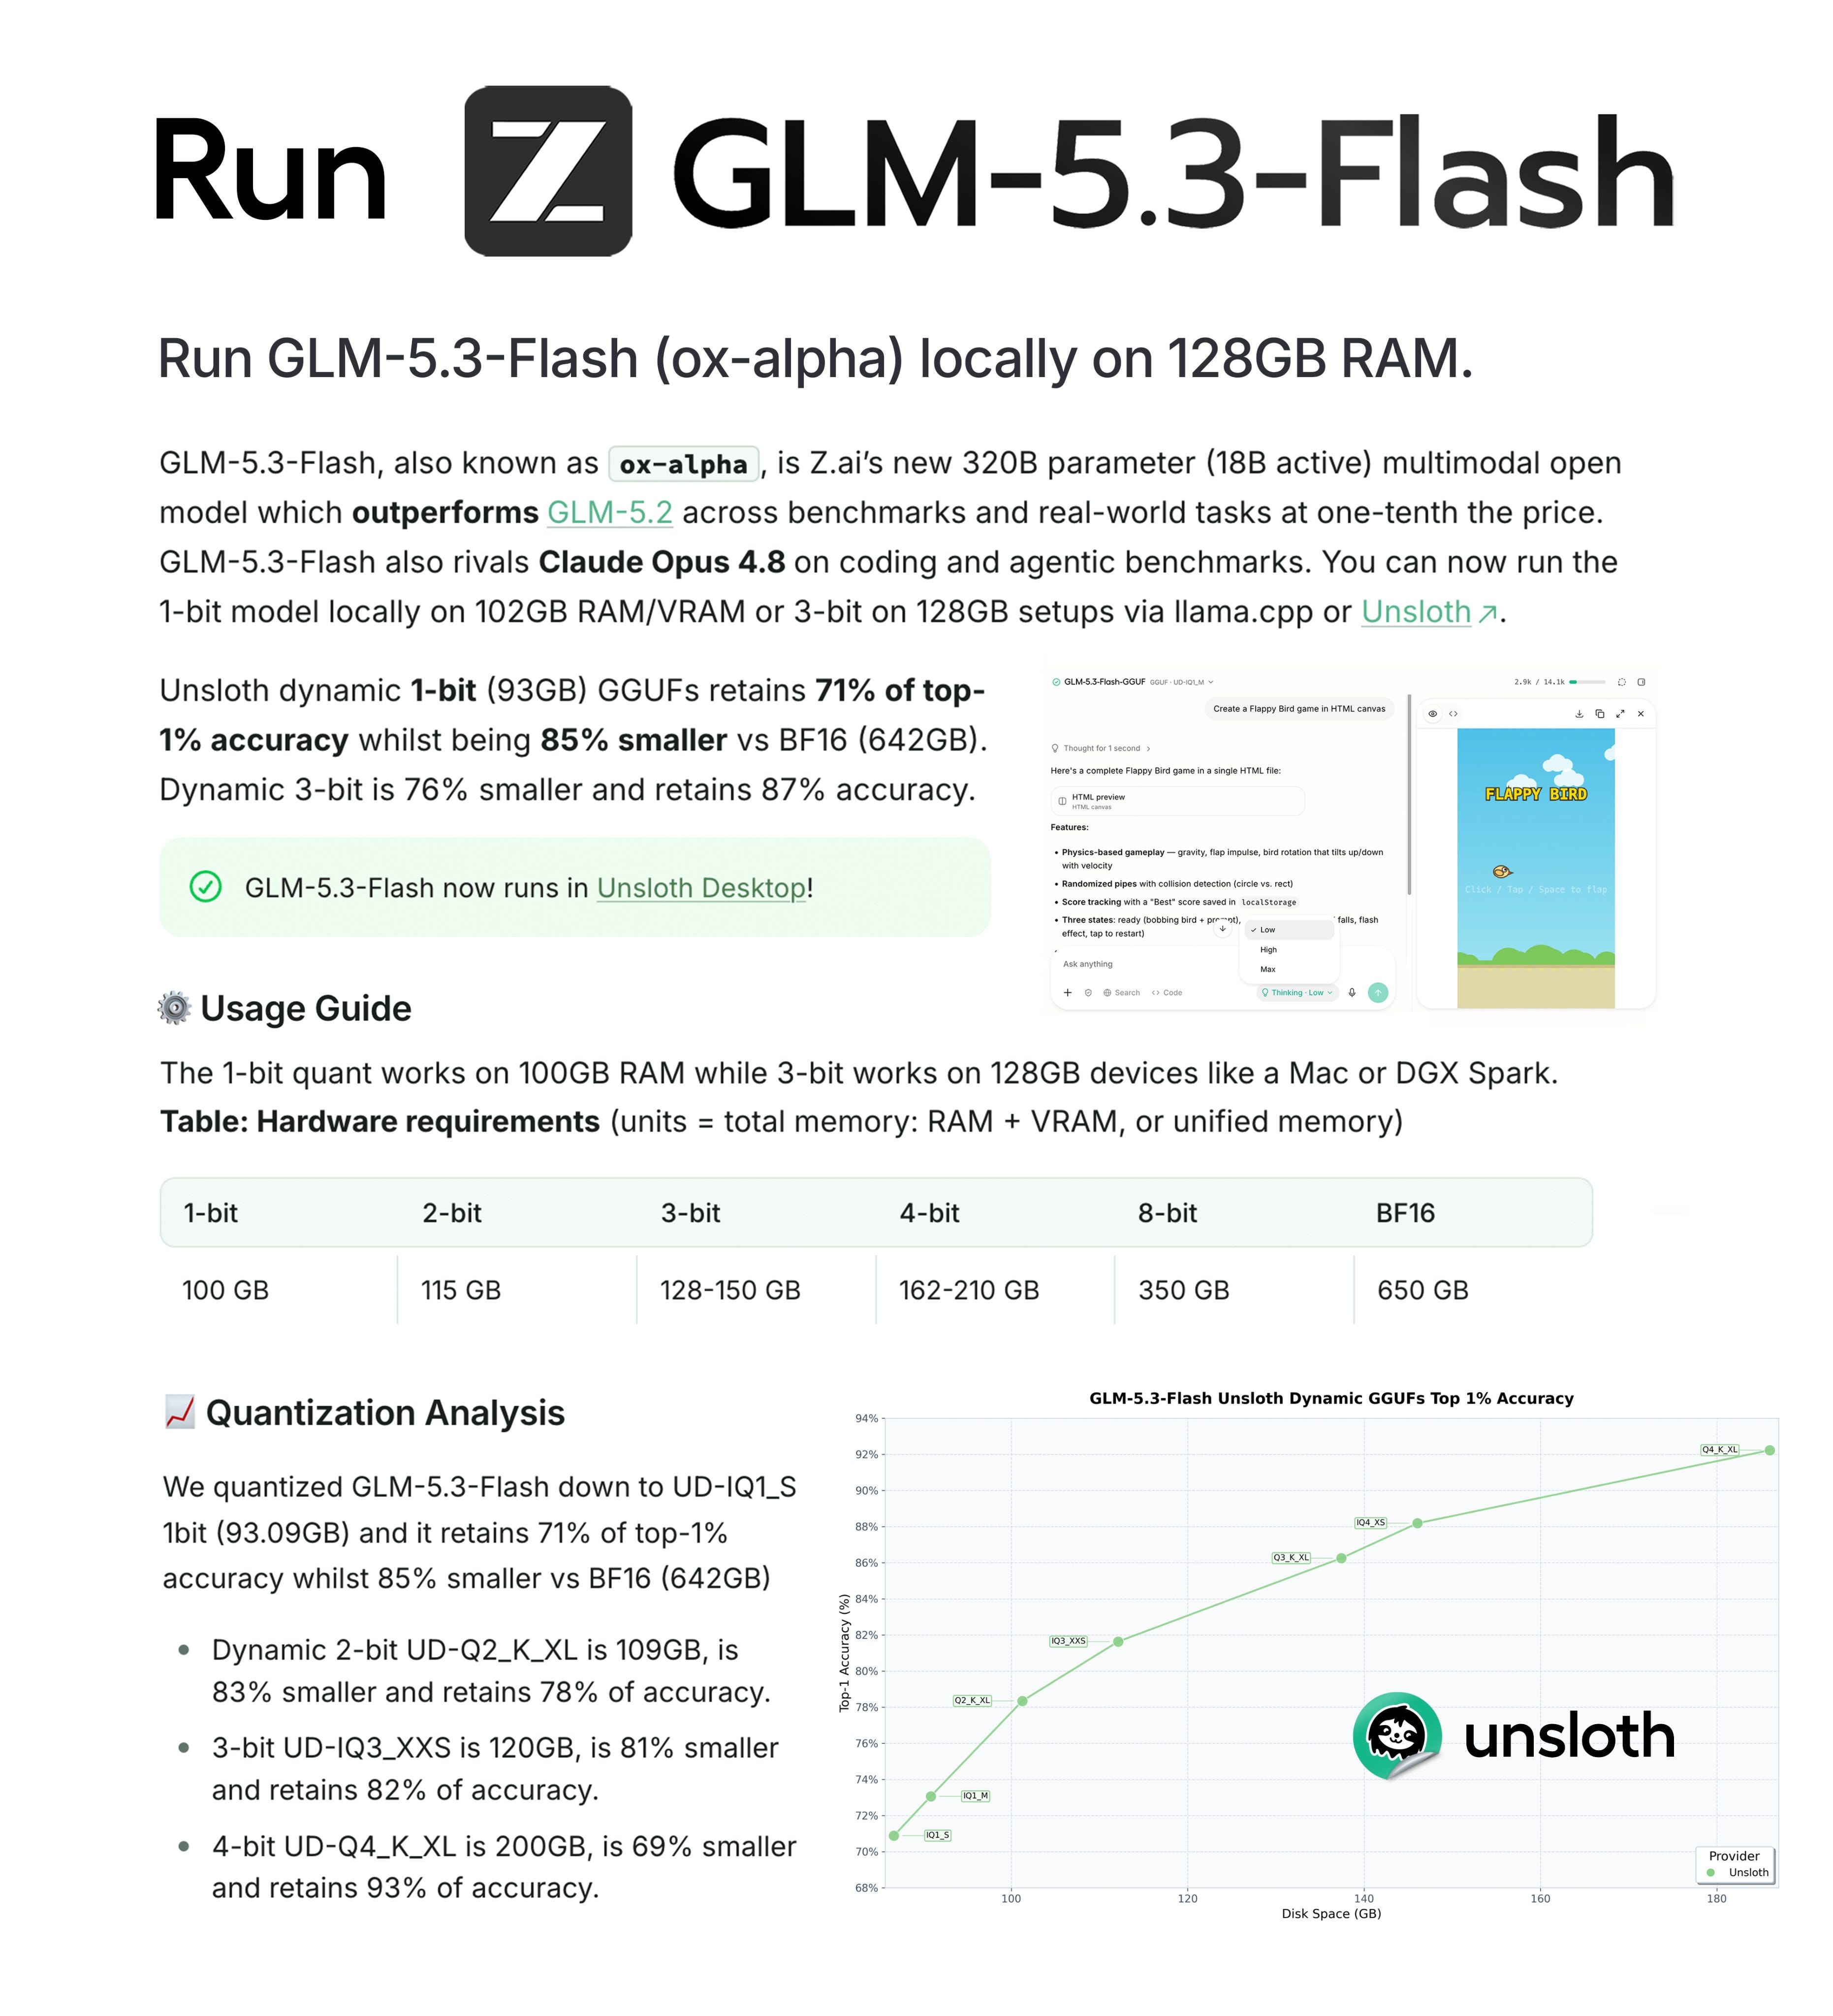
And because Unsloth shipped dynamic GGUF quantizations on Day 1, a 1-bit version now runs on a 100 GB machine, and a 3-bit version fits a 128 GB Mac or NVIDIA DGX Spark.
Then there is the claim that reaches past this particular model. Zhipu says the entire stealth week of Ox Alpha traffic was served on a cluster of roughly 100,000 Chinese-made AI chips, with no NVIDIA hardware involved. If that holds up at production quality, the infrastructure moat that U.S. export controls were built to protect is narrower than most investors assume, a shift readers of our piece on the leaked DeepSeek investor call have seen building from the inside.
This deep dive is the complete playbook on GLM-5.3-Flash: how it stacks up against Claude, GPT, Gemini, and DeepSeek on real benchmarks, what it costs, how to set it up in Claude Code and Cline, how and when to run it locally, five copy-paste prompts that unlock its full potential, and the risks every investor and founder has to underwrite before betting on it.
If you build, fund, or compete in AI, GLM-5.3-Flash just reset the price floor under your market, and you need to understand the most powerful open model available today.